Multimodal AI: How AI Is Learning to See, Hear, Speak and Understand
Artificial Intelligence is becoming more than just text-based technology. With Multimodal AI, machines can understand and work with different types of information, including text, images, audio, and video.
What Is Multimodal AI?
Multimodal AI refers to AI systems that can process multiple forms of data at the same time. Instead of only reading text, AI can now analyze an image, understand spoken language, watch a video, and combine this information to produce a useful response.
For example, you can show an AI a picture and ask what it contains, speak to it instead of typing, or provide a video and ask it to explain what happened.
How Does It Work?
Multimodal AI combines different types of input and uses AI models to understand the relationship between them.
It can:
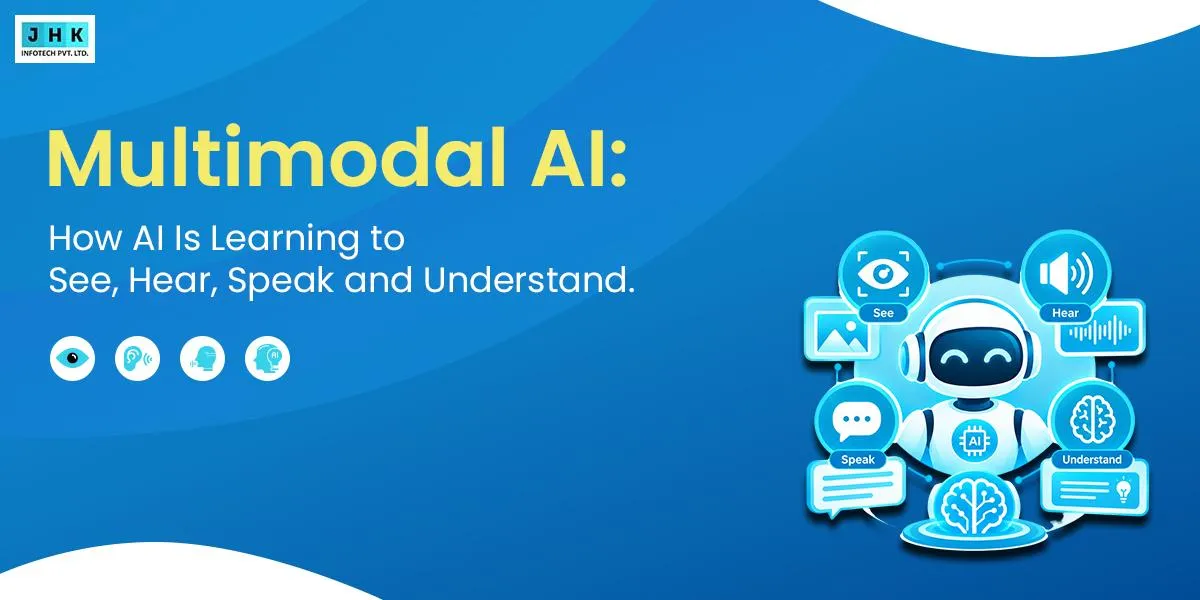
- 👁️ See – Understand images and visual information
- 👂 Hear – Recognize and interpret speech and sounds
- 🗣️ Speak – Communicate using natural voice
- 🧠 Understand – Connect information from different formats
This makes AI interactions feel more natural and human-like.
How Multimodal AI Actually Works
Multimodal AI systems work by converting different types of data into a shared mathematical space called an embedding space. Each modality — text, image, audio, or video — is first processed by a specialized encoder:
- Vision Encoder – Converts images or video frames into numerical representations.
- Audio Encoder – Transforms speech and sounds into features the model can understand.
- Text Encoder – Processes written language.
Once the data is converted into embeddings, a fusion mechanism combines them. This allows the model to understand relationships across modalities. For example, it can connect the words “a red car” with the actual visual appearance of a red car in an image.
Modern systems often use transformer-based architectures that can attend to information from multiple modalities at the same time, enabling more accurate reasoning and responses.
Popular Multimodal AI Models in 2026
Several powerful multimodal models are leading the field in 2026:
- GPT-4o / GPT-4.1 (OpenAI) – Excellent at real-time reasoning across text, images, and audio. Strong performance in conversational and analytical tasks.
- Gemini 1.5 & Gemini 2.0 (Google) – Known for very long context windows and strong multimodal understanding, especially with documents and video.
- Claude 3.5 / Claude 4 (Anthropic) – Highly capable at careful reasoning while handling images and complex documents.
- LLaVA, Qwen-VL, and other open-source models – Popular in research and custom applications because they can be fine-tuned and run more affordably.
These models show how multimodal AI has moved from experimental research into practical tools used by businesses and developers.
Why Is Multimodal AI Important?
Multimodal AI can make artificial intelligence more useful in everyday situations.
It can help with:
Education: Explain diagrams, videos, and spoken lessons. Students can upload diagrams, handwritten notes, or video lectures and receive clear explanations, making learning more interactive and personalized.
Healthcare:AI systems can analyze medical images (X-rays, CT scans, MRIs) together with doctor notes and lab reports to support faster and more accurate diagnosis.
Business: Understand documents, presentations, calls, and customer interactions.
Entertainment: Analyze and create content across multiple media formats.
Accessibility: Make technology easier to use through voice, vision, and other inputs.
The Future of Multimodal AI
The future of AI isn’t limited to typing questions into a chatbot. AI is moving toward systems that can see, hear, speak, reason, and interact with the world around us.
As multimodal AI continues to improve, our interaction with technology could become more natural, intelligent, and personalized.
Limitations of Multimodal AI
Despite its progress, Multimodal AI still faces several challenges:
- High Computational Cost – Processing images, audio, and video requires significantly more computing power than text-only models.
- Data Quality Issues – The model’s performance depends heavily on the quality and diversity of training data across modalities.
- Hallucinations – Sometimes the AI can generate incorrect connections between what it sees and what it says.
- Latency – Real-time processing of high-quality video and audio can still be slow on consumer devices.
- Privacy Concerns – Handling images, voice, and video raises stronger privacy and security considerations.
Understanding these limitations is important for realistic expectations and responsible use of the technology.
Multimodal AI vs Traditional AI
Here’s a clear comparison between the two approaches:
- Data Handling: Traditional AI usually works with only one type of data (mostly text). Multimodal AI can process text, images, audio, and video together.
- Understanding: Traditional models have limited context. Multimodal models can connect information across different formats, similar to how humans understand the world.
- Use Cases: Traditional AI is strong for pure language tasks. Multimodal AI is better for real-world applications that involve mixed data.
- Complexity: Multimodal systems require more computing power and training data but deliver richer and more flexible results.
Final Thought
AI is learning to understand the world the way humans do — through more than just words.
The era of multimodal AI has only just begun.
JHK Infotech — Exploring the Future of AI.
Written by the JHK Infotech AI Team. We research and explain emerging AI technologies to help businesses and developers understand practical applications of artificial intelligence.
Frequently Asked Questions
What is Multimodal AI?
Multimodal AI refers to artificial intelligence systems that can process and understand multiple types of data at the same time — including text, images, audio, and video — and combine them to generate useful responses.
How does Multimodal AI work?
It uses specialized models that convert different data types (vision, speech, text) into a shared representation space. The system then fuses this information so it can reason across modalities and produce coherent answers.
What are the main benefits of Multimodal AI?
Multimodal AI can understand and process multiple types of data at once — such as text, images, audio, and video. This allows it to provide more accurate, context-aware, and human-like responses compared to traditional text-only AI systems.
What are the limitations of Multimodal AI?
Current limitations include high computational cost, the need for large amounts of training data, occasional hallucinations when combining modalities, and challenges in real-time processing of high-quality video and audio.
How is Multimodal AI different from traditional AI?
Traditional AI usually works with only one type of data (mostly text). Multimodal AI can process and connect multiple data types simultaneously, which makes its understanding closer to how humans perceive the world.
Recent Post
-
September 16, 2026
Multimodal AI: How AI Is Learning to See, Hear, Speak and Understand
-
September 11, 2026
AI Employees: How Businesses Are Building Digital Workforces in 2026
-
September 7, 2026
What Is GEO? The Future of SEO in the Age of AI Search
-
-
February 26, 2026
AI Trends 2026: Latest AI Innovation, Developments & Predictions